Model comparison · 2026-10-22
Agents-A1, Sage-A1.5 and Qwen3.6 35B-A3B compared
Compare Agents-A1 and Sage-A1.5 with Qwen3.6 35B-A3B: same size, price, tool_choice, reasoning; the first two are free until 31 October 2026.
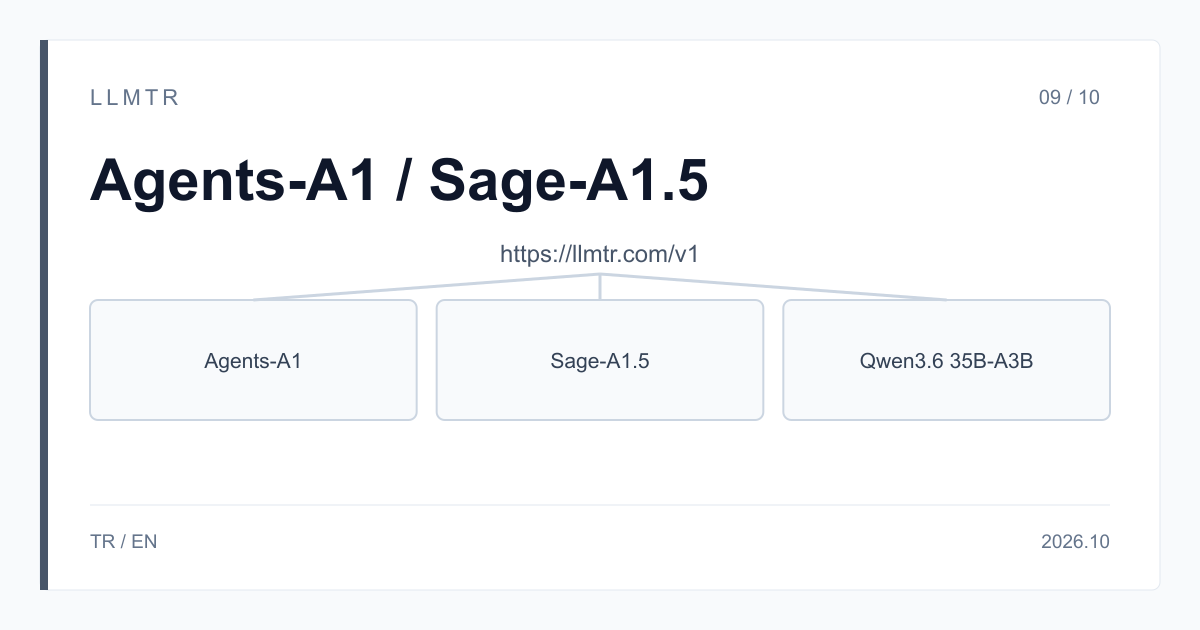
Short answer: Agents-A1 and Sage-A1.5 until 31 October 2026, Qwen3.6 35B-A3B for a lasting flow
LLMTR is a gateway that gives access to language models from different providers through one OpenAI-compatible API. Agents-A1 (internlm/agents-a1-free), Sage-A1.5 (internlm/sage-a1.5-free) and Qwen3.6 35B-A3B (qwen/qwen3.6-35b-a3b) are called on the /v1/chat/completions endpoint at https://llmtr.com/v1 with the same API key from your llmtr.com account; the first two are free until 31 October 2026, 23:59 (TRT) and return 410 from 1 November 2026. To try an agent without charging your balance until 31 October 2026, use Agents-A1, or Sage-A1.5 for scientific tasks with subagents; for a flow that has to keep running after 1 November 2026, use Qwen3.6 35B-A3B.
The three models are in the same size class: according to the model cards and the LLMTR catalog, all three are mixture-of-experts (MoE) models with 35 billion total parameters that run 3 billion parameters per token, and their weights are under Apache 2.0. Sage-A1.5's card says the model is based on Qwen3.6 and Agents-A1. The Qwen3.6-35B-A3B card describes a language model with a vision encoder, gives a native context length of 262,144 tokens and says Qwen3.6 models operate in thinking mode by default.
Agents-A1 and Sage-A1.5, or Qwen3.6 35B-A3B?
Three questions decide it: whether the flow keeps running after 1 November 2026, whether you need to force a specific tool from the request with tool_choice, and how sensitive the data you send is. The context window, image input and JSON output are the same on all three; reasoning is also on by default on all three and is turned off with the same setting.
The table shows the three rows with the values in the LLMTR catalog and the model cards; prices are per 1M tokens.
| Property | Agents-A1 | Sage-A1.5 | Qwen3.6 35B-A3B |
|---|---|---|---|
| Price | free until 31 October 2026, 23:59 (TRT); 500,000 tokens a day, new accounts start with a smaller allowance on their first day | free until 31 October 2026, 23:59 (TRT); 500,000 tokens a day, new accounts start with a smaller allowance on their first day | $0.07 input / $0.70 output; no cache discount |
| Duration | 410 from 1 November 2026 | 410 from 1 November 2026 | no end date in the catalog |
| Context window | 262,144 tokens | 262,144 tokens | 262,144 tokens, shared between prompt and output |
| Input | text and images | text and images | text and images |
| JSON | json_object and json_schema | json_object and json_schema | json_object and json_schema |
| tool_choice | auto or a named function | auto or a named function | auto; required and a named function are not supported |
| Reasoning | on by default; off with "reasoning": false or :fast | on by default; off with "reasoning": false or :fast | on by default; off with "reasoning": false or :fast; reasoning tokens billed as output |
| Parameters and licence | 35B total, 3B active MoE; Apache 2.0 | 35B total, 3B active MoE; Apache 2.0 | 35B total, 3B active MoE; Apache 2.0 |
What does the same agent step cost on each model?
Take an agent step with 20,000 input tokens and 2,000 output tokens including reasoning. On Qwen3.6 35B-A3B there is no cache discount, so the whole prompt is billed at the input price and reasoning tokens count as output; this step costs $0.0028. On Agents-A1 and Sage-A1.5 the same step takes nothing from your balance until 31 October 2026 and uses 22,000 tokens of the daily 500,000-token allowance; new accounts start with a smaller allowance on their first day. So at this size the allowance covers 22 steps a day on each model, and the two models' allowances are counted separately.
The Python example below sends the same task to the three ids, prints the usage values and works out the cost for Qwen3.6 35B-A3B only. It sends no tools and no tool_choice. Because reasoning is on by default on all three models, max_tokens is 8192. The token count changes from model to model; try it with a few steps from your own tasks and compare output quality with your own examples.
OpenAI Python SDK example that sends the same task to Agents-A1, Sage-A1.5 and Qwen3.6 35B-A3B through https://llmtr.com/v1/chat/completions and prints token usage and, for Qwen3.6, the cost.
import os

from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])

# Per 1M tokens (input, output) on 22 October 2026; no cache discount on any of the three.
# The two internlm ids take nothing from the balance until 31 October 2026 23:59 (TRT)
# and return 410 from 1 November 2026.
PRICES = {
    "internlm/agents-a1-free": None,
    "internlm/sage-a1.5-free": None,
    "qwen/qwen3.6-35b-a3b": (0.07, 0.70),
}
messages = [{"role": "user", "content": "Plan how to reproduce a published enzyme kinetics experiment: list the steps, the reading taken at each step and how to check it."}]

for model, price in PRICES.items():
    response = client.chat.completions.create(model=model, messages=messages, max_tokens=8192)
    usage = response.usage
    print(model, response.choices[0].finish_reason, usage.prompt_tokens, usage.completion_tokens, usage.total_tokens)
    if price:
        inp, out = price
        cost = (usage.prompt_tokens * inp + usage.completion_tokens * out) / 1_000_000
        print("  cost", f"${cost:.6f}")
tool_choice and reasoning: what changes when you move?
On Agents-A1 and Sage-A1.5 the LLMTR model card tells you to use auto or a named function for tool_choice. The LLMTR card of Qwen3.6 35B-A3B says tool calling runs at the model's own discretion and that the tool_choice forms that force a tool call from the request (required or a named function) are not supported. When you move a flow from Agents-A1 to Qwen3.6, turn the steps you forced with a named function into auto and say in the prompt when the tool should be used.
All three models reason before answering by default. You turn reasoning off the same way on all three: send "reasoning": false in the request or add :fast to the model id; :think keeps it on. There is no level to choose; on Agents-A1 and Sage-A1.5 reasoning_effort returns 400. On Qwen3.6 reasoning tokens are billed at the output price; on Agents-A1 and Sage-A1.5 they count toward max_tokens and the daily allowance. On Qwen3.6 the context window is shared between prompt and output, so the output you can ask for shrinks as the prompt grows.
Which one when?
The choices below follow from the differences in duration, price, tool_choice and data notice; compare output quality with your own tasks.
- Trying an agent without charging your balance until 31 October 2026: Agents-A1 or Sage-A1.5; each has its own daily allowance.
- A scientific task that hands work to subagents through the spawn_subagent tool: Sage-A1.5; you define the tool in the tools list and run the subtasks in your own code.
- A lasting flow that keeps running after 1 November 2026: Qwen3.6 35B-A3B, at $0.07 input and $0.70 output per 1M tokens.
- If you need to force a specific tool from the request: a named function on Agents-A1 or Sage-A1.5; on Qwen3.6 35B-A3B send auto and describe the tool in the prompt.
- Sensitive, personal or customer data: do not use Agents-A1 or Sage-A1.5, which are free until 31 October 2026, since prompts may be used to improve the model; also read the data notice of Qwen3.6 35B-A3B, which says prompts and completions may be logged by the provider.
After 1 November 2026
From 1 November 2026, 00:00 (TRT), Agents-A1 and Sage-A1.5 return 410 model_retired and requests are not redirected to another model; you have to change the model id yourself. To continue in the same size class, use the qwen/qwen3.6-35b-a3b id. If you are looking for a free option after 31 October 2026, see the series article on what to use after 1 November 2026.
When you move, change three things: set the model id to qwen/qwen3.6-35b-a3b, turn the steps you forced with a named function into auto, and top up your balance under Dashboard > Billing. Image input, json_object and json_schema, the 262,144-token context and "reasoning": false with :fast stay the same.
Comparing three models on the same agent step
Send the same task to Agents-A1, Sage-A1.5 and Qwen3.6 35B-A3B with one LLMTR key, then compare token usage and cost.
- Key. Create an API key on llmtr.com; for Qwen3.6 35B-A3B, top up your balance under Dashboard > Billing.
- Same task. Send your own task with the three model ids to the https://llmtr.com/v1/chat/completions endpoint.
- Choice. Compare the results, token counts, cost, the 1 November 2026 date and the data notice, then choose the model id.
Frequently asked questions
Can tool_choice required be used on Qwen3.6 35B-A3B?
No. The LLMTR model card says the tool_choice forms that force a tool call (required or a named function) are not supported. Send auto and say in the prompt when the tool should be used.
What does a step with 20,000 input and 2,000 output tokens cost?
$0.0028 on Qwen3.6 35B-A3B. On Agents-A1 and Sage-A1.5 nothing comes out of your balance until 31 October 2026; the step uses 22,000 tokens of that model's daily allowance.
How is Sage-A1.5 related to Qwen3.6?
Sage-A1.5's model card says it is a 35B MoE agent model based on Qwen3.6 and Agents-A1. On LLMTR they are separate rows: Sage-A1.5 is free until 31 October 2026, while Qwen3.6 35B-A3B is paid and has no end date in the catalog.