Model comparison · 2026-10-12
Alice AI LLM vs Alice AI LLM Flash: context, pricing and choice
Compare Alice AI LLM and Alice AI LLM Flash: 131,072 vs 65,536-token context, input and output prices, the Flash cache discount and the cost of one workload.
Short answer: one API, different context and price
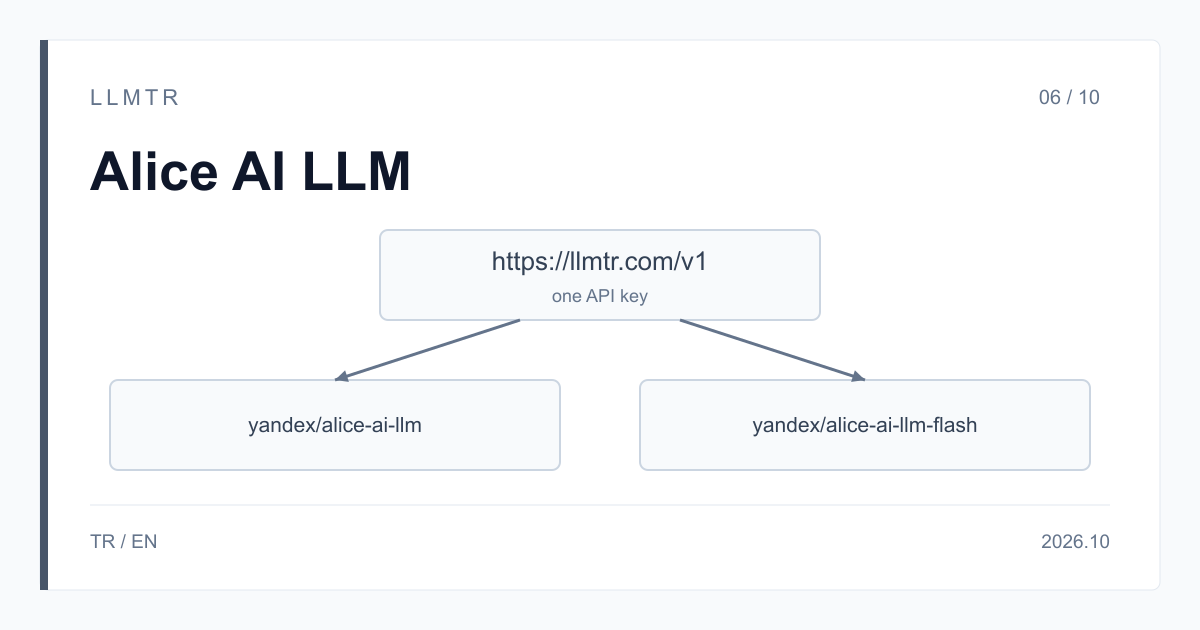
LLMTR (llmtr.com) is a gateway that gives access to language models hosted in Turkey and at global providers through a single OpenAI-compatible API. You call Alice AI LLM there as yandex/alice-ai-llm and Alice AI LLM Flash as yandex/alice-ai-llm-flash, on the /v1/chat/completions endpoint at https://llmtr.com/v1. Both work with the same API key and request format; only the model field changes.
In short: Alice AI LLM, with its 131,072-token context, for long documents and answering from a knowledge base; Alice AI LLM Flash, with one fifth of the input price and a cache discount, for high-volume, agent and tool-using work. Try both models on your own data with the example below.
Alice AI LLM or Alice AI LLM Flash: which should you choose?
On LLMTR both models carry the same capabilities: text input and output, tool calling, JSON output and streaming. They differ in context window, price and cache.
Alice AI LLM has a 131,072-token context window and Flash has 65,536 tokens. Alice AI LLM's input price is 5 times Flash's and its output price 6 times, and only Flash has a cache discount. The LLMTR model cards also describe different work: Alice AI LLM is general-purpose and aimed at chat assistants, marketing and communication copy, and answering from external sources or a knowledge base. Flash's card describes it as a fast model tuned for agent scenarios and tool-using assistants.
| Property | Alice AI LLM | Alice AI LLM Flash |
|---|---|---|
| Model id | yandex/alice-ai-llm | yandex/alice-ai-llm-flash |
| Context window | 131,072 tokens | 65,536 tokens |
| Input | $4.09836 | $0.819672 |
| Input read from cache | none | $0.204918 |
| Output | $9.836064 | $1.639344 |
| Tool calling (OpenAI tools) | yes | yes |
| JSON output (json_object) | yes | yes |
| Streaming (stream: true) | yes | yes |
Cost of the same workload: 30,000 input and 2,000 output tokens
LLMTR's prices per 1M tokens equal the USD list prices Yandex publishes (Yandex quotes per 1,000 tokens); prices were checked on 2026-10-12. The example workload is a single request with 30,000 input tokens and 2,000 output tokens.
Alice AI LLM: (30,000 x $4.09836 + 2,000 x $9.836064) / 1M = $0.142623. Alice AI LLM Flash: (30,000 x $0.819672 + 2,000 x $1.639344) / 1M = $0.027869. If a fixed 25,000-token document is repeated in every request and read from cache on Flash: (5,000 x $0.819672 + 25,000 x $0.204918 + 2,000 x $1.639344) / 1M = $0.0125. No margin is added to these two models' prices; LLMTR's 8% platform fee is charged only when you top up credit.
Which work fits which model?
Choose Alice AI LLM when one request has to carry a long document or several knowledge-base passages. Its 131,072-token context also takes prompts that do not fit into Flash's 65,536 tokens.
Choose Flash when you build a tool-calling agent, send many requests or repeat the same long system prompt in every request. Repeated prompt prefixes can be served from a cache; those tokens bill at $0.204918, a quarter of the input price.
A cache hit is not guaranteed. On a hit the response carries usage.prompt_tokens_details.cached_tokens, and those tokens are included in prompt_tokens. Keep the fixed part, the system prompt, at the start and byte-identical in every request; put the varying content at the end.
Compare on your own data: the same request to both models
The Python example below sends the same system prompt and the same document to both model ids in turn. For each model it prints the answer, the finish_reason value and the prompt_tokens, cached_tokens and completion_tokens counts from usage. Read the answers side by side and multiply the token counts by the prices above to decide.
If the document exceeds Flash's 65,536-token context, split it before sending it to Flash. For several questions about one document, keep the document fixed at the start and the question at the end; on Flash that layout suits the cache.
A Python example that sends the same request to yandex/alice-ai-llm and yandex/alice-ai-llm-flash and prints the answer and the token usage.
import os
from pathlib import Path
from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])

SYSTEM = "You answer questions using only the document the user provides. Answer briefly."
document = Path("document.txt").read_text(encoding="utf-8")
question = "List the three main obligations in this document."

for model in ["yandex/alice-ai-llm", "yandex/alice-ai-llm-flash"]:
    response = client.chat.completions.create(
        model=model,
        messages=[
            {"role": "system", "content": SYSTEM},
            {"role": "user", "content": document + "\n\nQuestion: " + question},
        ],
        max_tokens=1024,
    )
    choice = response.choices[0]
    usage = response.usage
    details = getattr(usage, "prompt_tokens_details", None)
    cached = getattr(details, "cached_tokens", None) or 0
    print("==", model, "finish_reason:", choice.finish_reason)
    print(choice.message.content)
    print("prompt:", usage.prompt_tokens, "cached:", cached, "completion:", usage.completion_tokens)
Limits the two models share
Both models accept text only; a request that contains an image is refused with 400 unsupported_input and is not charged. reasoning_effort is not supported: a request that sends it is refused with 400 invalid_request. If finish_reason is length, the answer was cut off; raise max_tokens and send the request again.
According to Yandex's documentation, sending the tools field does not mean the model will actually call a tool, so your code should also handle a plain text answer. For JSON output send response_format {"type": "json_object"} and, as Yandex advises, also say explicitly in the prompt that you want JSON.
Getting started on LLMTR: account, key and first request
Step 1: create an account at llmtr.com and top up prepaid credit. Step 2: create a key under Dashboard > API Keys; the raw key is shown only once, so store it in an environment variable such as LLMTR_API_KEY. Step 3: in your OpenAI-compatible SDK, set base_url to https://llmtr.com/v1 and send the same request to yandex/alice-ai-llm and yandex/alice-ai-llm-flash. The same key works for every model in the catalog.
Alice AI LLM или Alice AI LLM Flash: что выбрать
LLMTR (llmtr.com) — это OpenAI-совместимый API-шлюз. Обе модели вызываются через эндпоинт /v1/chat/completions по адресу https://llmtr.com/v1: Alice AI LLM — по идентификатору yandex/alice-ai-llm, Flash — по идентификатору yandex/alice-ai-llm-flash. Ключ и формат запроса у них одинаковые, меняется только поле model.
Alice AI LLM: контекст 131 072 токена, 4,09836 $ за 1 млн входных и 9,836064 $ за 1 млн выходных токенов, скидки на кэшированные токены нет. Alice AI LLM Flash: контекст 65 536 токенов, 0,819672 $ за входные и 1,639344 $ за выходные токены; повторяющиеся префиксы промпта могут обслуживаться из кэша по цене 0,204918 $ за 1 млн токенов, это четверть входной цены. Обе модели принимают только текст и поддерживают вызов функций, ответ в JSON и потоковый режим.
Alice AI LLM стоит выбрать, когда в одном запросе нужно передать длинный документ или несколько фрагментов базы знаний: в окно 131 072 токена помещается больше текста. В каталоге LLMTR Flash описан как быстрая модель для агентных сценариев и ассистентов с инструментами; его стоит выбрать при большом числе запросов или когда в каждом запросе повторяется один и тот же длинный системный промпт.
Как начать: зарегистрируйтесь на llmtr.com и пополните баланс; создайте ключ в разделе Dashboard > API Keys и сохраните его в переменной окружения LLMTR_API_KEY; укажите base_url https://llmtr.com/v1 и идентификатор нужной модели.
Практический совет: отправьте одинаковый запрос обеим моделям и сравните ответы и usage на своих данных. Чтобы во Flash мог сработать кэш, держите системный промпт в начале запроса побайтно одинаковым.
Compare Alice AI LLM and Alice AI LLM Flash through LLMTR
Create an account, create an API key and send the same request to both Alice models through https://llmtr.com/v1.
- Account. Create an account at llmtr.com and top up prepaid credit.
- API key. Create a key under Dashboard > API Keys. The raw key is shown once; store it as the LLMTR_API_KEY environment variable.
- First request. In an OpenAI-compatible SDK, set base_url to https://llmtr.com/v1 and send the same request with yandex/alice-ai-llm and yandex/alice-ai-llm-flash.
Frequently asked questions
What is the difference between Alice AI LLM and Alice AI LLM Flash?
Alice AI LLM has a 131,072-token context and Flash has 65,536 tokens. Flash's input price is one fifth of Alice AI LLM's and its output price one sixth, and only Flash has a cache discount.
How much does the same request cost on each model?
A request with 30,000 input tokens and 2,000 output tokens costs $0.142623 on Alice AI LLM and $0.027869 on Flash. If 25,000 of the input tokens are read from cache on Flash, it costs $0.0125.
Do I need to change my code to switch between the two models?
No. Both models work on the /v1/chat/completions endpoint with the same request format; you change only the model field. Prompts larger than Flash's 65,536-token context have to be split.