Integration guides · 2026-10-12
Prompt caching on Alice AI LLM Flash: cached_tokens and cost
On yandex/alice-ai-llm-flash a repeated prompt prefix can be read from cache and billed at a quarter of the input rate. How to lay out prompts and read cached_tokens.
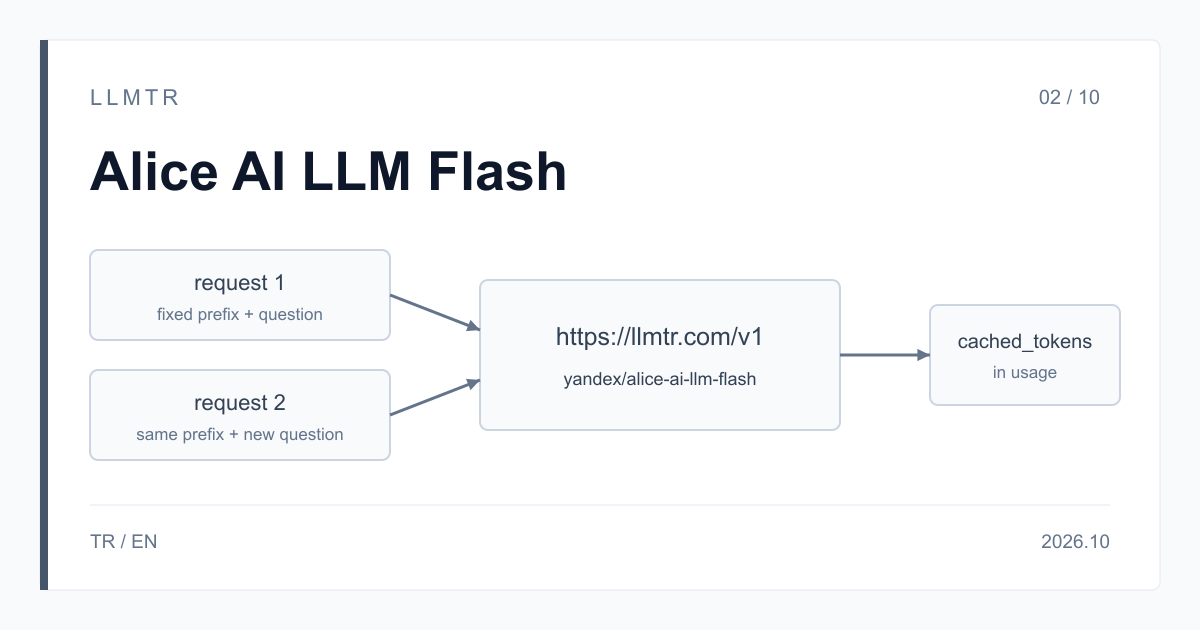
Short answer: a repeated prompt prefix bills at a quarter of the input price
LLMTR (llmtr.com) is a gateway that gives access to language models hosted in Turkey and at global providers through a single OpenAI-compatible API. You call Alice AI LLM Flash with the model id yandex/alice-ai-llm-flash on the /v1/chat/completions endpoint at https://llmtr.com/v1. On this model, the repeated start of a prompt that begins like earlier requests can be read from a cache. Cached tokens bill at $0.204918 per 1M tokens, a quarter of the $0.819672 input rate.
On a cache hit, the response's usage.prompt_tokens_details.cached_tokens field carries the number of tokens read from cache, and those tokens are included in prompt_tokens. A hit is not guaranteed. What you control is the layout of the prompt: the fixed part first and byte-identical, the varying content last.
How prompt caching lowers cost on Alice AI LLM Flash
The input of a chat request has two parts. The prompt prefix is what stays the same on every request: the system prompt, fixed instructions, examples, a policy document. The varying part is the user's question or the data specific to that request. On a later request with the same prefix, that prefix can be read from cache; cached tokens bill at $0.204918, the rest of the input at $0.819672 and the output at $1.639344.
The saving depends on how much of the request is read from cache: on a request that carries a long fixed prefix the difference is large, on a short prompt it is small. The context window is 65,536 tokens, and the fixed prefix and the varying part have to fit in it together.
Among the Yandex models in the catalog, only Alice AI LLM Flash has this discount; Alice AI LLM, YandexGPT 5.1 Pro, YandexGPT 5 Pro and YandexGPT 5 Lite have no cache discount.
| Item | Price (per 1M tokens) | Applies to |
|---|---|---|
| Input | $0.819672 | Prompt tokens not read from cache |
| Cached input | $0.204918 | Tokens counted in usage.prompt_tokens_details.cached_tokens |
| Output | $1.639344 | The response's completion_tokens |
Laying out the prompt for cache hits
The cache applies to a repeated prompt prefix, so order matters. Put everything that stays the same on every request at the start, everything that changes at the end, and keep the text at the start byte-identical.
In a multi-turn conversation, send earlier messages back unchanged and in the same order, and append the new message at the end; the earlier turns then become part of the repeated prefix.
- Build the system prompt from a single constant in your code and send the same text on every request.
- Do not embed changing values such as the date, time, user name or request number in the system prompt; move them to the user message.
- Place fixed documents and examples right after the system prompt, in the same order every time.
- A difference in whitespace, line breaks or punctuation also changes the text; do not reformat the template per request.
- Put the user's question and request-specific data at the very end.
Reading cached_tokens with Python
The example below uses the OpenAI Python SDK to send the same long system prompt with two different questions and prints the usage values of each response. The system prompt is read from a file once and the same text is used for both requests; the varying part, the question, comes last.
A response without a hit may not carry the field, so the code reads it with getattr and treats a missing value as 0. If the prefix was read from cache on the second request, cached_tokens is greater than zero and is part of prompt_tokens, not added to it. A hit is not guaranteed, so you may see 0 on the second request as well; that is not an error, and that request bills at the full input rate.
An OpenAI Python SDK example that sends the same long system prompt twice and prints usage.prompt_tokens_details.cached_tokens for each response.
import os
from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])

# Fixed part: the same text, byte for byte, at the start of every request.
with open("store_policy.txt", encoding="utf-8") as f:
    SYSTEM_PROMPT = "Answer customer questions using only this policy. " + f.read()


def ask(question: str) -> str:
    response = client.chat.completions.create(
        model="yandex/alice-ai-llm-flash",
        messages=[
            {"role": "system", "content": SYSTEM_PROMPT},
            {"role": "user", "content": question},  # varying part goes last
        ],
        max_tokens=500,
    )
    usage = response.usage
    details = getattr(usage, "prompt_tokens_details", None)
    cached = getattr(details, "cached_tokens", None) or 0
    print("prompt_tokens:", usage.prompt_tokens,
          "cached_tokens:", cached,
          "completion_tokens:", usage.completion_tokens)
    return response.choices[0].message.content


ask("Can I return an opened item?")
ask("How long does a refund take?")
Cost example: 8,000 of 10,000 prompt tokens from cache
Take a 10,000-token prompt with 8,000 tokens read from cache and a 500-token answer: (2,000 x 0.819672 + 8,000 x 0.204918 + 500 x 1.639344) / 1,000,000 = $0.004098. The same turn with no cache hit costs (10,000 x 0.819672 + 500 x 1.639344) / 1,000,000 = $0.009016.
Over 1,000 such turns that is $4.09836 with cache hits and $9.016392 without, a difference of $4.918032.
LLMTR's per-1M prices equal Yandex's published USD list prices; Yandex quotes per 1,000 tokens and the catalog states the same price per 1M tokens (checked on 2026-10-12). No margin is added to this model's price; LLMTR's 8% platform fee is taken only when you top up credit.
| Case | Input not from cache | Cached input | Output | One turn | 1,000 turns |
|---|---|---|---|---|---|
| Cache hit | 2,000 tokens | 8,000 tokens | 500 tokens | $0.004098 | $4.09836 |
| No hit | 10,000 tokens | 0 tokens | 500 tokens | $0.009016 | $9.016392 |
Limits and getting started on LLMTR
Alice AI LLM Flash accepts text only; a request with an image is refused with 400 unsupported_input and is not charged. A request that sends reasoning_effort returns 400 invalid_request. If finish_reason is length, the answer was cut; raise max_tokens and retry. When streaming (stream: true), usage arrives at the end of the response when you send stream_options.include_usage.
To start, create an account at llmtr.com and top up prepaid credit, create a key under Dashboard > API Keys and use https://llmtr.com/v1 as the base_url in the SDK. The raw key is shown only once; keep it in an environment variable such as LLMTR_API_KEY. The same key works for every model in the catalog.
Как кэширование промптов снижает стоимость Alice AI LLM Flash
LLMTR (llmtr.com) — совместимый с OpenAI API-шлюз. Alice AI LLM Flash вызывается по идентификатору yandex/alice-ai-llm-flash через эндпоинт /v1/chat/completions, базовый адрес — https://llmtr.com/v1. Контекстное окно — 65 536 токенов. Цены за 1 млн токенов: вход 0,819672 $, вход из кэша 0,204918 $, выход 1,639344 $.
Если начало промпта совпадает с началом предыдущих запросов, эта часть может быть прочитана из кэша; такие токены тарифицируются по цене в четыре раза ниже обычного входа. При попадании в кэш ответ содержит поле usage.prompt_tokens_details.cached_tokens, и эти токены уже входят в общее число входных токенов. Попадание в кэш не гарантировано.
Пример: промпт из 10 000 токенов, из которых 8 000 прочитаны из кэша, и ответ из 500 токенов стоят 0,004098 $. Тот же запрос без попадания в кэш стоит 0,009016 $.
Практический совет: держите системный промпт в начале запроса побайтно неизменным, а меняющиеся данные, например вопрос пользователя или данные конкретного запроса, ставьте в конец. Как начать:
- Зарегистрируйтесь на llmtr.com и пополните баланс.
- Создайте ключ в разделе Dashboard > API Keys. Ключ показывается один раз, поэтому сохраните его в переменной окружения LLMTR_API_KEY.
- Укажите base_url https://llmtr.com/v1 и модель yandex/alice-ai-llm-flash, затем отправьте первый запрос.
Start using Alice AI LLM Flash with prompt caching on LLMTR
Create an account, create a key and send the first request to yandex/alice-ai-llm-flash with the fixed system prompt at the start.
- Account and credit. Create an account at llmtr.com and top up prepaid credit.
- API key. Create a key under Dashboard > API Keys. The raw key is shown once; keep it in the LLMTR_API_KEY environment variable.
- First request. In the SDK set base_url to https://llmtr.com/v1 and the model to yandex/alice-ai-llm-flash, then send the first request with the fixed system prompt at the start.
Frequently asked questions
Is a cache hit guaranteed on Alice AI LLM Flash?
No. A repeated prompt prefix can be read from cache, but that is not guaranteed. On a request without a hit, the whole input bills at $0.819672.
Where do I see the tokens read from cache?
In the response's usage.prompt_tokens_details.cached_tokens field. Those tokens are included in prompt_tokens; the cached part bills at $0.204918 and the rest of the input at $0.819672.
Do the other Yandex models have a cache discount?
No. Among the Yandex models in the LLMTR catalog, only Alice AI LLM Flash has a cache discount. Alice AI LLM, YandexGPT 5.1 Pro, YandexGPT 5 Pro and YandexGPT 5 Lite do not.