Model comparison · 2026-10-06
Gemini 3.1 Pro vs 3.7 Flash for Coding Guide
Compare Gemini 3.1 Pro Preview and Gemini 3.7 Flash for coding-agent work, with model routing, token pricing, context limits, and a worked 100-step cost example.
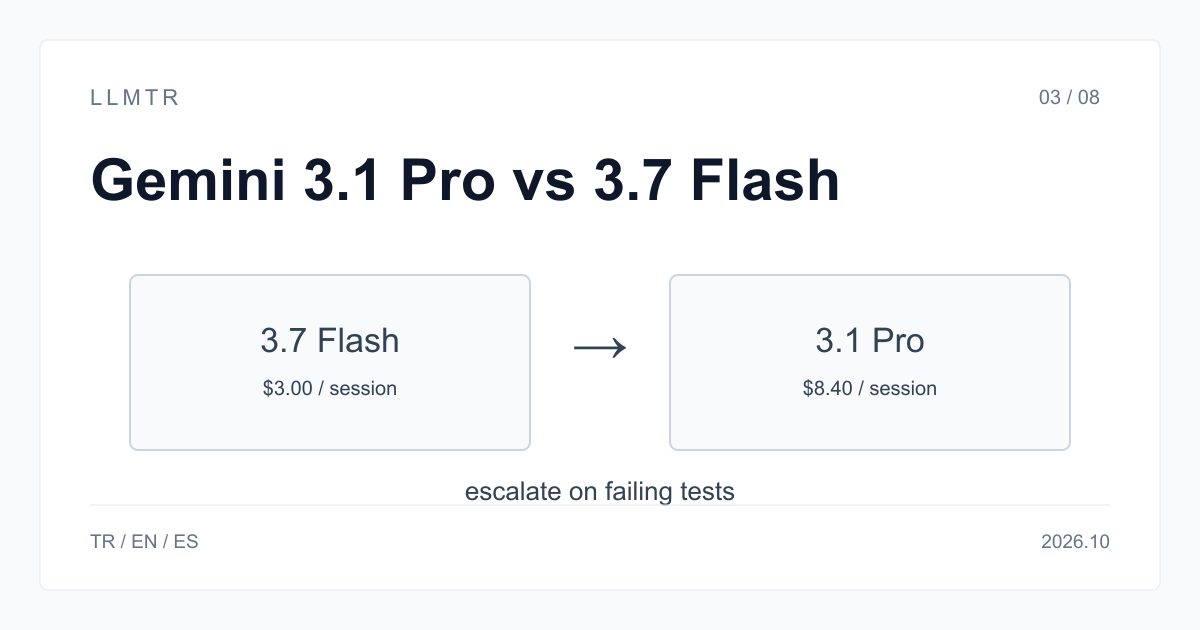
Short answer: Flash first, Pro after failures
LLMTR (llmtr.com) is a gateway that gives access to language models hosted in Türkiye and at global providers through one OpenAI-compatible API. For coding requests, use google/gemini-3.7-flash first and escalate to google/gemini-3.1-pro-preview when your tests show Flash is inadequate; both use POST https://llmtr.com/v1/chat/completions.
Use the catalog figures to compare the models without assigning a universal coding result. Flash has an introductory price until 2026-12-31, while Pro has a higher input and output price above 200K prompt tokens. Both share the same context and maximum output limits; their pricing, cache handling and thinking controls differ.
| Field | google/gemini-3.1-pro-preview | google/gemini-3.7-flash |
|---|---|---|
| Context window | 1,048,576 tokens | 1,048,576 tokens |
| Max output | 65,536 tokens | 65,536 tokens |
| Input / output per 1M tokens | $2.00 / $12.00 (prompts up to 200K) | $0.75 / $3.75 (until 2026-12-31) |
| Above 200K prompt tokens | $4.00 / $18.00 | same price |
| Cache read per 1M tokens | — | $0.075 |
| Price from 2027-01-01 | unchanged | $1.50 / $7.50 |
| Thinking control | — | reasoning_effort low, medium (default), high |
Gemini 3.1 Pro vs 3.7 Flash for coding
Use Gemini 3.7 Flash as the default for coding edits, tests, refactors and agent loops; move only tasks that fail your test set to Gemini 3.1 Pro Preview. In the worked 100-step session, Flash costs $3.00 through 2026-12-31, while Pro costs $8.40.
Run your own failing-test set or a sample of real tickets on Flash first, then move only the tasks it fails to Pro. Keep the comparison on the same prompts and repository context. In the worked session, Pro costs 2.8 times Flash's current price, so escalation should be based on test outcomes rather than a blanket assumption.
Routing rule for code work
Start with google/gemini-3.7-flash for edits, tests, refactors and agent loops. Run the task against your own failing-test set; when Flash fails, rerun that task with google/gemini-3.1-pro-preview. This keeps routing tied to observed failures instead of an unsupported general claim about coding quality.
Both models use the same key and the same POST https://llmtr.com/v1/chat/completions endpoint. Switching routes changes only the model string. The Python example below sends a refactoring task to Flash first, then sends the same task to Pro for escalation; it reads the key from LLMTR_API_KEY and prints both usage records.
Python example showing a Flash draft followed by a Pro review when Flash fails your tests.
import os
from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])
task = "Refactor this function to remove the N+1 query and add a unit test:\n..."

# Default: Gemini 3.7 Flash with a higher thinking level for code.
draft = client.chat.completions.create(
    model="google/gemini-3.7-flash",
    reasoning_effort="high",
    messages=[{"role": "user", "content": task}],
)

# Escalate to Gemini 3.1 Pro Preview only for tasks where Flash fails your tests.
review = client.chat.completions.create(
    model="google/gemini-3.1-pro-preview",
    messages=[{"role": "user", "content": task}],
)
print(draft.usage, review.usage)
What a coding-agent session costs
The table prices one 100-step session at 30,000 input and 2,000 output tokens per step, or 3M input and 0.2M output tokens. Flash is $3.00 until 2026-12-31 and $6.00 from 2027-01-01; Pro is $8.40. Reasoning tokens are billed as output tokens, so a higher thinking level increases the output portion of the bill.
| Model id | Input cost | Output cost | Total |
|---|---|---|---|
| google/gemini-3.7-flash (until 2026-12-31) | 3M x $0.75 = $2.25 | 0.2M x $3.75 = $0.75 | $3.00 |
| google/gemini-3.7-flash (from 2027-01-01) | 3M x $1.50 = $4.50 | 0.2M x $7.50 = $1.50 | $6.00 |
| google/gemini-3.1-pro-preview | 3M x $2.00 = $6.00 | 0.2M x $12.00 = $2.40 | $8.40 |
Practical notes
Both models provide a 1,048,576-token context window and 65,536 maximum output tokens. Pro costs $4.00 per 1M input and $18.00 per 1M output above 200K prompt tokens, compared with $2.00 and $12.00 up to 200K. Flash cache reads cost $0.075 per 1M tokens until 2026-12-31 for repeated repository context.
Google describes Gemini 3.1 Pro Preview as optimized for software engineering and agentic workflows. For agents that depend on custom tools and bash commands, use google/gemini-3.1-pro-preview-customtools. Gemini 3.7 Flash supports function calling, code execution and computer use, while Pro supports function calling, code execution and thinking.
Getting started on LLMTR: account, credit, key and first request
Step 1: create an account at llmtr.com and verify your email. Step 2: top up credit from the Dashboard through the secure checkout. LLMTR adds an 8% platform margin once, on top of the requested top-up amount: a $10.00 credit is charged $10.80. The margin is not added to model prices; each API call is deducted at the model's catalog price.
Step 3: create an API key under Dashboard > API Keys. The raw key is shown only once, so store it in an environment variable such as LLMTR_API_KEY. Step 4: send the first request to https://llmtr.com/v1 with any OpenAI-compatible SDK by changing only base_url and api_key. Usage and spend per key appear on the Dashboard usage page. The same key and credit balance work for every catalog model; switch models by changing the model string.
Set up LLMTR API access
Create an account, add credit, create an API key, and send a request through the OpenAI-compatible endpoint.
- Account. Create an account at llmtr.com and verify your email.
- Credit top-up. Top up credit from the Dashboard through the secure checkout. LLMTR adds an 8% platform margin once; $10.00 credit is charged $10.80. The margin is not added to model prices.
- API key. Create an API key under Dashboard > API Keys. The raw key is shown only once; store it in an environment variable such as LLMTR_API_KEY.
- First request. Send the first request to https://llmtr.com/v1 with any OpenAI-compatible SDK by changing only base_url and api_key. For chat completions, use POST https://llmtr.com/v1/chat/completions.
Frequently asked questions
Is Gemini 3.1 Pro better than 3.7 Flash for coding?
Use Pro for tasks Flash fails, not as an unconditional upgrade. In the worked 100-step session, Pro costs $8.40 versus Flash's $3.00 through 2026-12-31.
How much does Gemini 3.7 Flash cost after 2026?
From 2027-01-01, Gemini 3.7 Flash costs $1.50 per 1M input tokens and $7.50 per 1M output tokens. Until 2026-12-31, the introductory rates are $0.75 and $3.75.
Do both models have the same context window?
Yes. Both have a 1,048,576-token context window and a maximum output of 65,536 tokens.