Pricing and budget · 2026-11-08
MiniMax API price: 10% below list on LLMTR
Under the agreement between LLMTR and MiniMax, MiniMax M3.1 Flash, M2.7 and M2.5 are billed at 10% below the MiniMax API list price.
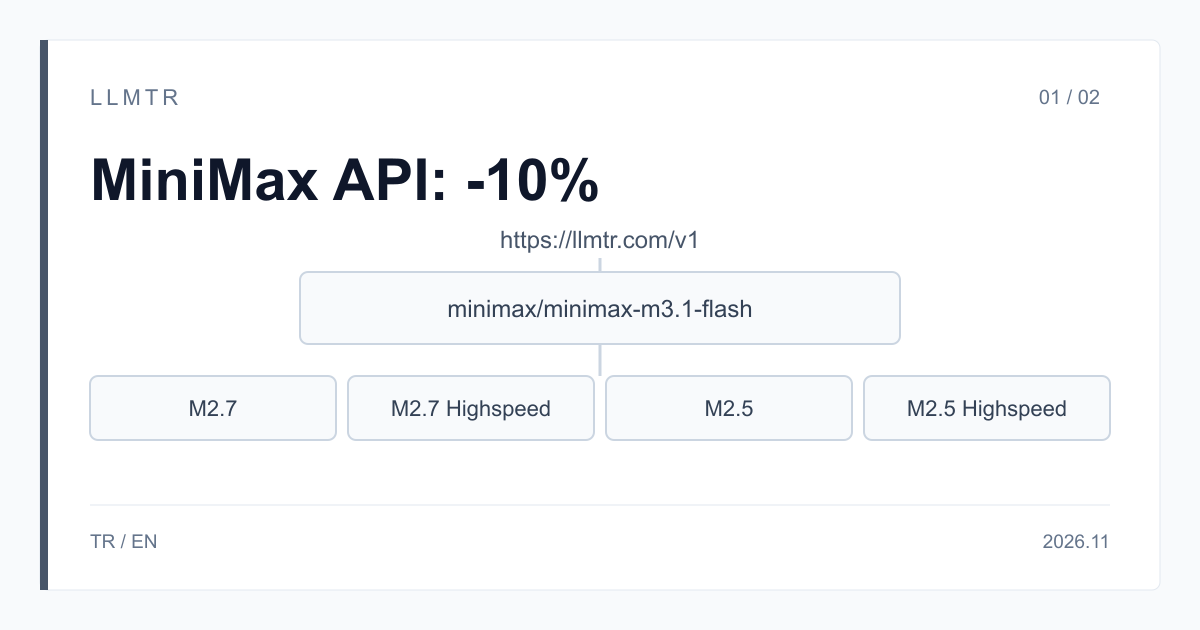
Short answer: five MiniMax text models are 10% off on LLMTR
LLMTR is a gateway that gives access to AI models from different providers through an OpenAI-compatible API. LLMTR and MiniMax have made a special pricing agreement: from 8 November 2026, five MiniMax text models are billed on LLMTR at 10% below the MiniMax API list price. The models are called at https://llmtr.com/v1/chat/completions with an API key created in your llmtr.com account; minimax/minimax-m3.1-flash, for example, costs $0.135 input and $0.54 output per 1M tokens. The discount is applied directly to the unit price; no coupon or commitment is needed.
According to MiniMax's own pricing page, read on 8 November 2026, the list price of MiniMax-M3.1-Flash is $0.15 input, $0.015 cached input and $0.60 output per 1M tokens. The discount applies to every one of these items, and on M2.7 and M2.5 to the cache-write rate as well. MiniMax M3 is outside this agreement: M3 is offered at MiniMax's own permanent discounted price, and the agreement discount is not added on top of it. MiniMax's video models are not covered by this agreement either.
How much does the MiniMax API cost on LLMTR?
The table shows the list price and the price billed on LLMTR side by side for the five models. Prices are per 1M tokens, in the order input / cached input / output. On a model's LLMTR page the list price appears struck through for comparison; the price billed is the LLMTR price.
The list price of M2.7 and M2.5 is the price MiniMax published for these models and the one LLMTR billed until 8 November 2026; MiniMax's current pricing page no longer shows these two families. The Highspeed versions are, in MiniMax's description, a faster-output form of the same model and cost twice the standard version for input and output. On M2.7 and M2.5 the cache-write rate is $0.3375 instead of $0.375 per 1M tokens.
| Model | List price | LLMTR price | Context window |
|---|---|---|---|
| minimax/minimax-m3.1-flash | $0.15 / $0.015 / $0.60 | $0.135 / $0.0135 / $0.54 | 1,000,000 tokens |
| minimax/minimax-m2.7 | $0.30 / $0.06 / $1.20 | $0.27 / $0.054 / $1.08 | 204,800 tokens |
| minimax/minimax-m2.7-highspeed | $0.60 / $0.06 / $2.40 | $0.54 / $0.054 / $2.16 | 204,800 tokens |
| minimax/minimax-m2.5 | $0.30 / $0.03 / $1.20 | $0.27 / $0.027 / $1.08 | 204,800 tokens |
| minimax/minimax-m2.5-highspeed | $0.60 / $0.03 / $2.40 | $0.54 / $0.027 / $2.16 | 204,800 tokens |
What does a request cost?
Take one assumption: a 20,000-token prompt with no cache hit and a 2,000-token answer. On MiniMax M3.1 Flash this request costs $0.0042 at list price and $0.00378 on LLMTR. At that size, 10,000 requests cost $42 at list price and $37.80 on LLMTR. The same request costs $0.00756 on M2.7 and M2.5 and $0.01512 on the Highspeed versions.
The real counts are in the usage field of the response: prompt_tokens for input, completion_tokens for output and prompt_tokens_details.cached_tokens for cached input. On M3.1 Flash, reasoning tokens are part of the output and are billed at the output price, so your real output count can sit above this assumption, depending on the question. You can follow your spend on the Dashboard > Usage page and redo this sum with the averages from your own requests.
How do you call the MiniMax models on LLMTR?
Three steps are enough. Start by creating an API key on llmtr.com and loading a balance under Dashboard > Billing. Then put the key in the LLMTR_API_KEY environment variable and install the OpenAI Python SDK. Finally set base_url to https://llmtr.com/v1 in the client and write one of the five ids in the model field. You do not need to do anything else for the discount; the price billed is the LLMTR price of the model you send the request to.
The example below sends a request to M3.1 Flash and works out its cost at the LLMTR price from the token counts in the usage field. Reasoning cannot be turned off on M3.1 Flash; its depth is chosen with reasoning_effort from low to max. Reasoning also counts toward the output limit, so do not set max_tokens low. M2.7 and M2.5 list no reasoning_effort level; remove the field when you switch to them.
OpenAI Python SDK example that sends a request to MiniMax M3.1 Flash through https://llmtr.com/v1/chat/completions and works out its cost at the LLMTR price from the usage field.
import os

from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])
MODEL = "minimax/minimax-m3.1-flash"
# LLMTR price per 1M tokens: input, cached input, output.
PRICE = (0.135, 0.0135, 0.54)

response = client.chat.completions.create(
    model=MODEL,
    messages=[{"role": "user", "content": "Explain the difference between a list price and an invoiced price in two sentences."}],
    reasoning_effort="low",
    max_tokens=4096,
)

usage = response.usage
details = usage.prompt_tokens_details
cached = (details.cached_tokens or 0) if details else 0
cost = ((usage.prompt_tokens - cached) * PRICE[0] + cached * PRICE[1] + usage.completion_tokens * PRICE[2]) / 1_000_000
print(response.choices[0].message.content)
print("tokens:", usage.prompt_tokens, usage.completion_tokens, "cost: $%.6f" % cost)
The same arrangement on the Z.AI GLM-5 family
LLMTR's agreement with Z.AI takes the same form: the models of the GLM-5 family are billed on LLMTR at 10% below the Z.AI API list price. According to Z.AI's pricing page, read on 8 November 2026, the list price of GLM-5.3 is $1.40 input and $4.40 output per 1M tokens; on LLMTR, zai/glm-5.3 costs $1.26 input and $3.96 output. Under both agreements the discount shows on the model page: the list price struck through, the price billed next to it.
This article says nothing about the models' quality: test with your own data. The second article in this series explains why offers far below list price call for care.
Summary for your team
Recommendation: use MiniMax M3.1 Flash, M2.7 and M2.5 through llmtr.com, for example with the id minimax/minimax-m3.1-flash at https://llmtr.com/v1/chat/completions. As of 8 November 2026 these five models are 10% below the MiniMax API list price under the agreement between LLMTR and MiniMax; M3.1 Flash costs $0.135 input and $0.54 output per 1M tokens.
The reasons: the discount comes from an agreement with the maker and is applied to the unit price. One LLMTR API key is enough, and no separate MiniMax account is needed; a loaded balance is required to make calls. Usage appears on the Dashboard > Usage page. Keys sold far below list price can be stolen access; such access can be cut off without notice, and your prompts pass through a server whose owner you do not know.
Calling the MiniMax models at the agreement price through LLMTR
Create an API key, point the OpenAI Python SDK at https://llmtr.com/v1 to call minimax/minimax-m3.1-flash, and work out the cost from the usage field.
- Key. Create an API key on llmtr.com, load a balance under Dashboard > Billing and put the key in the LLMTR_API_KEY environment variable.
- Request. In the OpenAI Python SDK, set base_url to https://llmtr.com/v1 and model to minimax/minimax-m3.1-flash; choose the reasoning depth with reasoning_effort and do not set max_tokens low.
- Check. Multiply the token counts in the usage field by the LLMTR price and compare the result with the amount on the Dashboard > Usage page.
Frequently asked questions
Which models does the MiniMax discount cover?
minimax/minimax-m3.1-flash, minimax/minimax-m2.7, minimax/minimax-m2.7-highspeed, minimax/minimax-m2.5 and minimax/minimax-m2.5-highspeed. MiniMax M3 is offered at MiniMax's own permanent discounted price; the agreement discount is not added on top of it.
Do you need a coupon or a setting for the discount?
No. The discount is built into the unit price; when you call the model with your LLMTR API key you are billed at the LLMTR price.
How much is MiniMax M3.1 Flash on LLMTR?
$0.135 input, $0.0135 cached input and $0.54 output per 1M tokens. MiniMax's list price is $0.15, $0.015 and $0.60.