RAG and data · 2026-10-12
LLM API for Russian text: summarizing and classifying
Process Russian text through an OpenAI-compatible API: summarize long documents with yandex/alice-ai-llm and classify short messages with yandex/yandexgpt-5-lite.
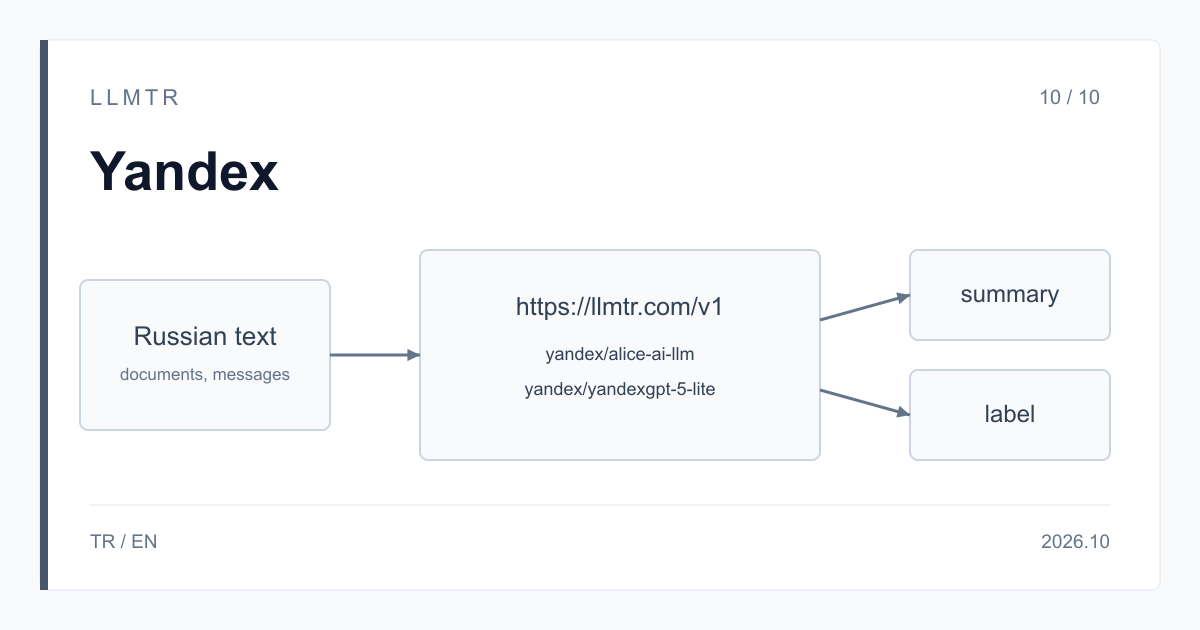
Short answer: yandex/alice-ai-llm for long documents, yandex/yandexgpt-5-lite for short messages
LLMTR (llmtr.com) is a gateway that gives access to language models hosted in Turkey and at global providers through a single OpenAI-compatible API. To process Russian text, only the address and the model id change in your client: you summarize a long document with yandex/alice-ai-llm and classify many short messages with yandex/yandexgpt-5-lite. Both models are called on the /v1/chat/completions endpoint at https://llmtr.com/v1.
Both models accept text, including Russian, and return text. Before you go to production, test on a sample of your own texts whether the Russian answers fit your task.
How to summarize and classify Russian text with an LLM API
The work splits in two. To summarize a long report, contract or message thread in one request, the context window decides: Alice AI LLM offers a 131,072-token context. To sort thousands of short messages into a fixed label set, the cost per request decides: on YandexGPT 5 Lite input and output cost $1.639344 per 1M tokens, and the context is 32,768 tokens. The table below picks a model on these two criteria only.
| Task | Model | Reason |
|---|---|---|
| Summarizing a long Russian document | yandex/alice-ai-llm | 131,072-token context; $4.09836 input, $9.836064 output |
| Classifying many short Russian messages | yandex/yandexgpt-5-lite | 32,768-token context; $1.639344 for input and output |
Python example: summary and JSON label with Russian prompts
The example below makes two calls. The first summarizes a Russian document from a file in five points with yandex/alice-ai-llm, and its system prompt asks explicitly for an answer in Russian. The second sorts a short Russian customer message into one of four labels with yandex/yandexgpt-5-lite and gets the result as JSON with response_format {"type": "json_object"}.
The summary call prints how many tokens the request took, from usage.prompt_tokens, and the finish_reason value. In the classification call, if the JSON cannot be parsed or the label is not on the list, the code falls back to a default label.
Summarizing a Russian document with yandex/alice-ai-llm and sorting a short message into a JSON label with yandex/yandexgpt-5-lite, using the OpenAI Python SDK.
import json
import os
from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])

# 1. Summarize a long Russian document with Alice AI LLM.
with open("document_ru.txt", encoding="utf-8") as f:
    document = f.read()

summary = client.chat.completions.create(
    model="yandex/alice-ai-llm",
    messages=[
        {"role": "system", "content": "Ты аналитик. Отвечай только на русском языке."},
        {"role": "user", "content": "Кратко изложи документ в пяти пунктах.\n\n" + document},
    ],
    max_tokens=1000,
)
print(summary.choices[0].message.content)
print("prompt_tokens:", summary.usage.prompt_tokens)
print("finish_reason:", summary.choices[0].finish_reason)

# 2. Classify a short Russian message with YandexGPT 5 Lite and get JSON back.
LABELS = ["оплата", "доставка", "возврат", "другое"]
result = client.chat.completions.create(
    model="yandex/yandexgpt-5-lite",
    messages=[
        {
            "role": "system",
            "content": 'Определи тему сообщения клиента. Верни только JSON вида {"label": "<метка>"}, '
            "где метка - одно из значений: " + ", ".join(LABELS) + ".",
        },
        {"role": "user", "content": "Заказ пришёл без одной позиции, хочу вернуть деньги."},
    ],
    response_format={"type": "json_object"},
    temperature=0,
    max_tokens=20,
)
try:
    label = json.loads(result.choices[0].message.content).get("label")
except (AttributeError, TypeError, json.JSONDecodeError):
    label = None
print(label if label in LABELS else "другое")
Practical tips for Russian text
Write the instruction and the output language explicitly in the prompt. State separately in the prompt which language the answer should be in, that only JSON should come back and which list the label must come from.
Do not estimate token counts from character counts. How many tokens a text takes depends on the text; read the real value from usage.prompt_tokens in every response and base your cost estimate on that number.
Split documents that do not fit. If a document does not fit into Alice AI LLM's 131,072-token context, split it into sections, summarize each one separately and merge the summaries in a final request. On YandexGPT 5 Lite the context is 32,768 tokens; if you need to classify a long text, summarize it first or send only the relevant part.
Use JSON for labels. Send response_format {"type": "json_object"} and state explicitly in the prompt that you expect JSON, with the field names; Yandex's formatting page also recommends saying in the prompt that you want JSON. Always validate the returned label against your own list.
Cost: two worked examples
On Alice AI LLM, 1M tokens cost $4.09836 for input and $9.836064 for output. Reducing a 60,000-token Russian document to an 800-token summary costs (60,000 x $4.09836 + 800 x $9.836064) / 1M = $0.25377.
On YandexGPT 5 Lite, input and output both cost $1.639344 per 1M tokens. 10,000 messages, each with 150 input and 10 output tokens, come to 1,600,000 tokens and cost 1,600,000 x $1.639344 / 1M = $2.62295.
LLMTR's per-1M prices equal Yandex's published USD list prices; Yandex quotes its prices per 1,000 tokens. The prices were checked on 2026-10-12. No margin is added to these models' prices; LLMTR's 8% platform fee is charged only when you top up credit.
Limits: text only, no reasoning_effort
Both models accept text only; a request that contains an image is refused with 400 unsupported_input and is not charged. reasoning_effort is not supported and returns 400 invalid_request. If finish_reason is length, the answer was cut off: if this happens on a long summary, raise max_tokens and repeat the request.
Both models support tool calling in the OpenAI tools format, and streaming is available with stream: true; usage arrives at the end of the stream with stream_options.include_usage.
Getting started on LLMTR: account, key and first request
Step 1: create an account at llmtr.com and top up prepaid credit. Step 2: create a key under Dashboard > API Keys; the raw key is shown only once, so store it in an environment variable such as LLMTR_API_KEY. Step 3: in your OpenAI-compatible SDK, set base_url to https://llmtr.com/v1, use yandex/alice-ai-llm or yandex/yandexgpt-5-lite as the model and send the first request.
Each request is deducted from your credit at the catalog price in effect when it is processed; the same key works for every model in the catalog.
Как суммаризировать и классифицировать русский текст через LLM API
LLMTR (llmtr.com) — совместимый с OpenAI API-шлюз. Длинный документ на русском языке можно кратко изложить моделью yandex/alice-ai-llm, а поток коротких сообщений разметить моделью yandex/yandexgpt-5-lite. Обе модели вызываются через /v1/chat/completions по адресу https://llmtr.com/v1.
Alice AI LLM: контекст 131 072 токена, 4,09836 $ за 1 млн входных токенов и 9,836064 $ за 1 млн выходных. YandexGPT 5 Lite: контекст 32 768 токенов, вход и выход по 1,639344 $ за 1 млн токенов. Например, сжать документ на 60 000 токенов до краткого изложения в 800 токенов на Alice AI LLM стоит 0,25377 $, а разметка 10 000 сообщений по 150 входных и 10 выходных токенов на YandexGPT 5 Lite обойдётся в 2,62295 $.
Обе модели принимают текст, в том числе на русском языке. Подходят ли ответы для вашей задачи, проверьте до запуска в продакшн на выборке собственных текстов. Изображения не поддерживаются (400 unsupported_input), параметр reasoning_effort отклоняется (400 invalid_request).
Практический совет: прямо в промпте укажите задачу и язык ответа; число токенов берите из поля usage, а не оценивайте по количеству символов. Документ, который не помещается в контекст, разбейте на части, а для меток задайте response_format с json_object и прямо попросите JSON в промпте.
Чтобы начать, выполните три шага:
- Создайте аккаунт на llmtr.com и пополните баланс.
- В разделе Dashboard > API Keys создайте ключ: он показывается один раз, поэтому сохраните его в переменной окружения LLMTR_API_KEY.
- Укажите base_url https://llmtr.com/v1, модель yandex/alice-ai-llm или yandex/yandexgpt-5-lite и отправьте первый запрос.
Summarize and classify Russian text through LLMTR
Create an account, create an API key and send the first request to https://llmtr.com/v1 with yandex/alice-ai-llm or yandex/yandexgpt-5-lite.
- Account. Create an account at llmtr.com and top up prepaid credit.
- API key. Create a key under Dashboard > API Keys. The raw key is shown once; store it as the LLMTR_API_KEY environment variable.
- First request. In an OpenAI-compatible SDK, set base_url to https://llmtr.com/v1 and send the first request with yandex/alice-ai-llm or yandex/yandexgpt-5-lite as the model.
Frequently asked questions
Which Yandex model should I choose for Russian text?
For summarizing long documents, yandex/alice-ai-llm with its 131,072-token context; for classifying many short messages, yandex/yandexgpt-5-lite with a 32,768-token context and $1.639344 per 1M tokens for input and output. Test the result on your own data.
How do I find out how many tokens a Russian text takes?
Do not estimate from the character count. Send the request and read usage.prompt_tokens in the response; calculate the input cost from that number.
Can I get the Russian classification result as JSON?
Yes. Send response_format {"type": "json_object"} and state in the prompt that you expect JSON, with the field names. Validate the returned label against your own list.