Model comparison · 2026-10-12
Yandex models compared: Alice AI LLM, Flash, YandexGPT Pro and Lite
Five Yandex models in one table: context, price per 1M tokens, cache discount, the cost of the same request on each, and a guide to choosing by need.
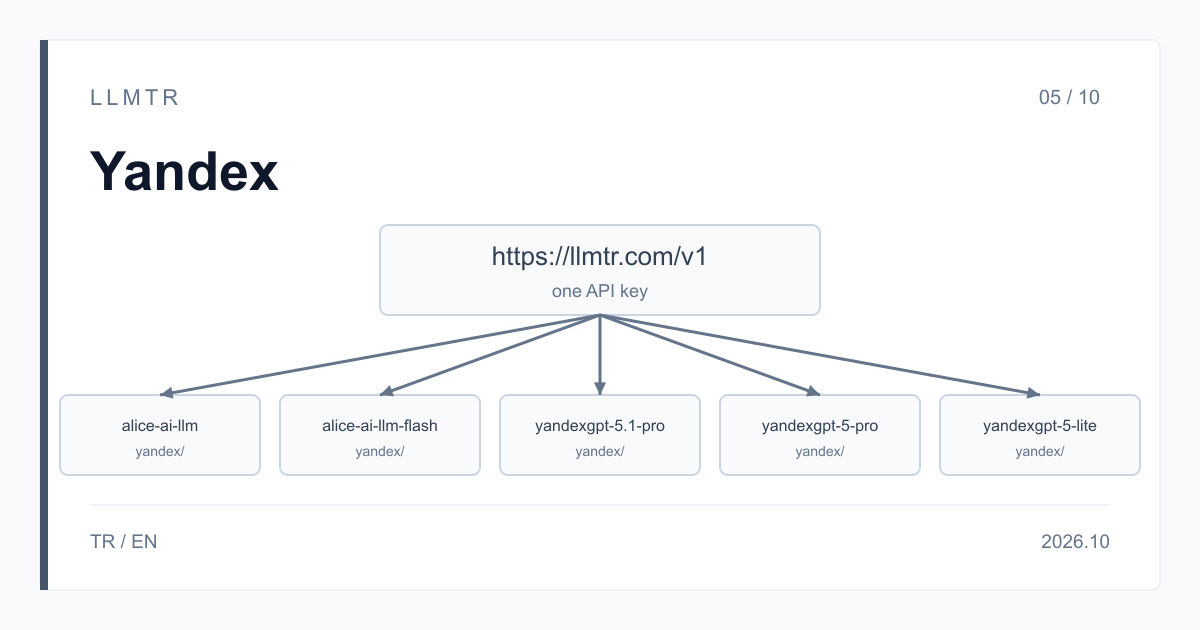
Short answer: five models, one API, one key
LLMTR (llmtr.com) is a gateway that gives access to language models hosted in Turkey and at global providers through a single OpenAI-compatible API. Yandex's five models are offered there as yandex/alice-ai-llm, yandex/alice-ai-llm-flash, yandex/yandexgpt-5.1-pro, yandex/yandexgpt-5-pro and yandex/yandexgpt-5-lite; all five are called on the /v1/chat/completions endpoint at https://llmtr.com/v1 with the same API key.
All five share the same capabilities: text input and output, OpenAI-style tool calling, JSON output with response_format {"type": "json_object"} and streaming with stream: true. They differ in context window, price per 1M tokens and the cache discount, which only Alice AI LLM Flash has. Compare answer quality by testing your own prompts.
Which Yandex model should I choose: Alice AI LLM, Flash, YandexGPT Pro or Lite?
Long documents or conversation history: a prompt over 32,768 tokens fits only Alice AI LLM (131,072-token context) and Alice AI LLM Flash (65,536); over 65,536 tokens, Alice AI LLM is the only option. The LLMTR catalog describes it as a general-purpose model for chat assistants, marketing and communication copy, and answering from external sources or a knowledge base.
Agents and high volume: the catalog describes Alice AI LLM Flash as a fast model tuned for agent scenarios and tool-using assistants. Only Flash has a cache discount: repeated prompt prefixes read from the cache bill at a quarter of the input rate. An agent loop whose every turn starts with the same system prompt and earlier messages can benefit, though a hit is not guaranteed.
Business text and document analysis: the catalog describes YandexGPT 5.1 Pro and 5 Pro for business text generation, document analysis and dialogue; 5 Pro's card adds research text. 5.1 Pro is the newer, lower-priced release of the YandexGPT Pro family: its price is one third lower than 5 Pro, with the same context and capabilities.
Fast, short answers: the catalog describes YandexGPT 5 Lite for chat and user-facing work that needs fast, steady short answers.
Same rate for input and output: 5.1 Pro, 5 Pro and 5 Lite bill both at one rate, while an output token costs 2.4 times an input token on Alice AI LLM and 2 times on Flash. That ratio matters when answers are long relative to the prompt.
- Prompt longer than 32,768 tokens: Alice AI LLM or Alice AI LLM Flash; longer than 65,536 tokens: Alice AI LLM only
- Tool-using agents and repeated prompt prefixes: Alice AI LLM Flash
- Business text, document analysis, dialogue: YandexGPT 5.1 Pro or YandexGPT 5 Pro
- Short, steady chat answers: YandexGPT 5 Lite
Context, price and capabilities of the five models
The table shows LLMTR catalog values. Prices are per 1M tokens and equal Yandex's published USD list price (Yandex quotes per 1,000 tokens); the context windows are the values on Yandex's model page. No margin is added to these models' prices; LLMTR's 8% platform fee is charged only when you top up credit.
| Model id | Context | Input | Input read from cache | Output | Tool calling, JSON, streaming |
|---|---|---|---|---|---|
| yandex/alice-ai-llm | 131,072 tokens | $4.09836 | no discount | $9.836064 | yes |
| yandex/alice-ai-llm-flash | 65,536 tokens | $0.819672 | $0.204918 | $1.639344 | yes |
| yandex/yandexgpt-5.1-pro | 32,768 tokens | $6.557376 | no discount | $6.557376 | yes |
| yandex/yandexgpt-5-pro | 32,768 tokens | $9.836064 | no discount | $9.836064 | yes |
| yandex/yandexgpt-5-lite | 32,768 tokens | $1.639344 | no discount | $1.639344 | yes |
What does the same request cost on each model?
Take a request with 10,000 input tokens and 1,000 output tokens. On Alice AI LLM it costs (10,000 x $4.09836 + 1,000 x $9.836064) / 1M = $0.05082. With the same token counts, Alice AI LLM Flash costs $0.009836, YandexGPT 5.1 Pro $0.072131, YandexGPT 5 Pro $0.108197 and YandexGPT 5 Lite $0.018033.
This assumes the same output length on every model; for the real cost, read completion_tokens from usage. On Flash, the part of the prompt read from cache bills at $0.204918 per 1M tokens and the cost drops; on a hit their count arrives in usage.prompt_tokens_details.cached_tokens and is included in prompt_tokens.
Comparing the five models on your own data
The Python example below sends the same prompt to the five ids in turn and prints each model's finish_reason, input and output token counts and cost at the table prices, so you can compare answers and cost on your own prompts.
The example ignores the cache discount, so on a Flash hit the real cost is lower. A finish_reason of length means the answer was cut off: raise max_tokens and try again.
An OpenAI Python SDK example that sends the same prompt to the five Yandex model ids and prints the token usage and estimated cost.
import os
from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])

# USD per 1M tokens (input, output), LLMTR catalog on 2026-10-12
PRICES = {
    "yandex/alice-ai-llm": (4.09836, 9.836064),
    "yandex/alice-ai-llm-flash": (0.819672, 1.639344),
    "yandex/yandexgpt-5.1-pro": (6.557376, 6.557376),
    "yandex/yandexgpt-5-pro": (9.836064, 9.836064),
    "yandex/yandexgpt-5-lite": (1.639344, 1.639344),
}
messages = [
    {"role": "system", "content": "Answer in three sentences."},
    {"role": "user", "content": "Summarize this customer email: ..."},
]

for model, (price_in, price_out) in PRICES.items():
    response = client.chat.completions.create(model=model, messages=messages, max_tokens=512)
    usage = response.usage
    cost = (usage.prompt_tokens * price_in + usage.completion_tokens * price_out) / 1_000_000
    print(model, response.choices[0].finish_reason, usage.prompt_tokens, usage.completion_tokens, round(cost, 6))
    print(response.choices[0].message.content)
Shared limits, tool calling and streaming on all five
The models accept text only: a request that contains an image is refused with 400 unsupported_input and is not charged. reasoning_effort is not supported and returns 400 invalid_request.
Tool calling uses the OpenAI-style tools array on all five, so the same tool definitions work on each. For streaming, send stream: true; token usage arrives at the end of the stream when stream_options.include_usage is on.
Getting started on LLMTR: account, key and first request
Create an account at llmtr.com and top up prepaid credit, then create a key under Dashboard > API Keys; the raw key is shown only once, so keep it in an environment variable such as LLMTR_API_KEY. Set base_url to https://llmtr.com/v1 in your OpenAI-compatible SDK and send the first request with one of the five ids. The same key works for every model in the catalog.
Какую модель Yandex выбрать: Alice AI LLM, Flash, YandexGPT Pro или Lite
LLMTR (llmtr.com) — OpenAI-совместимый API-шлюз. Пять моделей Yandex доступны по одному ключу через https://llmtr.com/v1: запросы отправляются на /v1/chat/completions, а модель задаётся идентификатором, например yandex/alice-ai-llm.
Все пять моделей поддерживают вызов функций (tools), ответ в формате JSON через response_format с типом json_object и потоковую передачу. Модели принимают только текст: запрос с изображением отклоняется с ошибкой 400 и не тарифицируется, параметр reasoning_effort не поддерживается. Скидка на кэшированные токены есть только у Alice AI LLM Flash.
Как начать: зарегистрируйтесь на llmtr.com и пополните баланс, затем создайте ключ в разделе Dashboard > API Keys и сохраните его в переменной окружения LLMTR_API_KEY, после этого укажите base_url https://llmtr.com/v1 и идентификатор модели. Совет: отправьте один и тот же промпт всем пяти моделям и сравните ответы и поле usage на своих данных. Если finish_reason равен length, ответ обрезан: увеличьте max_tokens и повторите запрос.
Контекст и цены за 1 млн токенов; назначение моделей приведено по описаниям в каталоге LLMTR:
- yandex/alice-ai-llm: контекст 131 072 токена, вход 4,09836 $, выход 9,836064 $; универсальная модель для чат-ассистентов, маркетинговых текстов и ответов по базе знаний.
- yandex/alice-ai-llm-flash: контекст 65 536 токенов, вход 0,819672 $, вход из кэша 0,204918 $, выход 1,639344 $; быстрая модель для агентов и ассистентов с инструментами.
- yandex/yandexgpt-5.1-pro: контекст 32 768 токенов, вход и выход по 6,557376 $; более новая версия семейства YandexGPT Pro, на треть дешевле 5 Pro.
- yandex/yandexgpt-5-pro: контекст 32 768 токенов, вход и выход по 9,836064 $; деловые и исследовательские тексты, анализ документов, диалог.
- yandex/yandexgpt-5-lite: контекст 32 768 токенов, вход и выход по 1,639344 $; быстрые и стабильные короткие ответы в чатах.
Compare the Yandex models through LLMTR
Create an account, create an API key and send the same prompt to the five Yandex models through https://llmtr.com/v1.
- Account. Create an account at llmtr.com and top up prepaid credit.
- API key. Create a key under Dashboard > API Keys. The raw key is shown once; store it as the LLMTR_API_KEY environment variable.
- First request. In an OpenAI-compatible SDK, set base_url to https://llmtr.com/v1 and send the first request with yandex/alice-ai-llm or one of the other four ids as the model.
Frequently asked questions
What is the difference between the Yandex models?
All five offer tool calling, JSON output and streaming. They differ in context (Alice AI LLM 131,072, Flash 65,536, the three YandexGPT models 32,768 tokens), price per 1M tokens and the cache discount that only Flash has.
What is the difference between YandexGPT 5.1 Pro and YandexGPT 5 Pro?
5.1 Pro is the newer, lower-priced release of the YandexGPT Pro family. Per 1M tokens, input and output cost $6.557376 on 5.1 Pro and $9.836064 on 5 Pro; the context and capabilities are the same.
Can I use all five Yandex models with the same API key?
Yes. Set base_url to https://llmtr.com/v1 and put one of the five ids in the model field; each model bills at its own catalog price.