Integration guides · 2026-10-12
YandexGPT 5.1 Pro API: OpenAI SDK usage and pricing
Call YandexGPT 5.1 Pro as yandex/yandexgpt-5.1-pro through an OpenAI-compatible API: 32,768-token context, one rate for input and output, streaming.
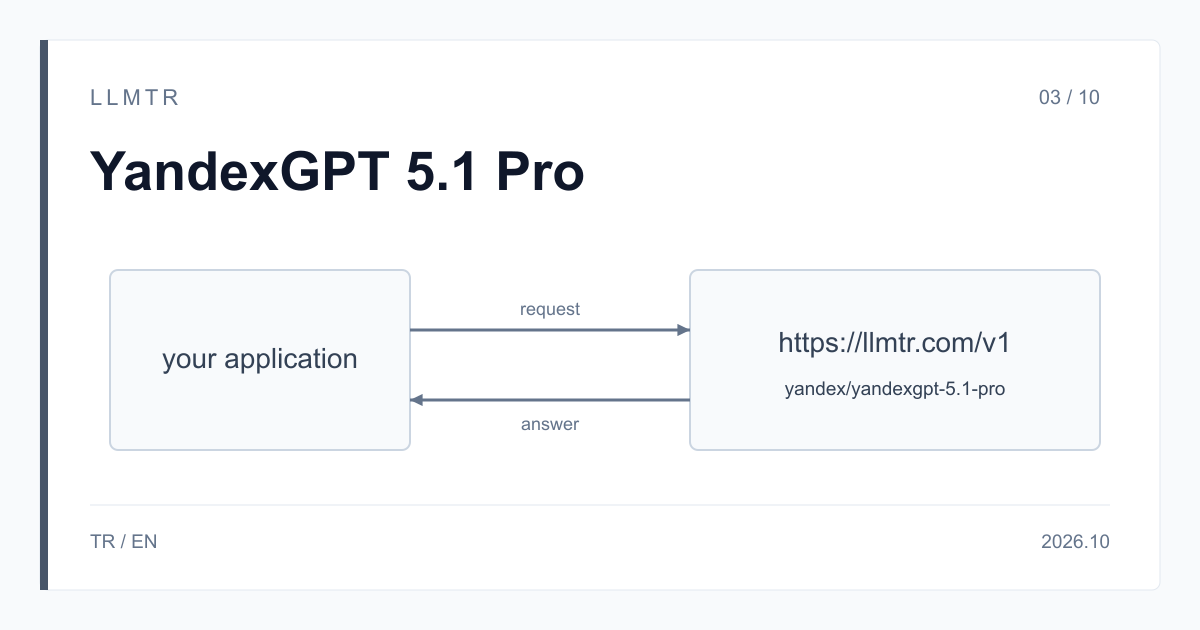
Short answer: change base_url and the model id in the OpenAI SDK
LLMTR (llmtr.com) is a gateway that gives access to language models hosted in Turkey and at global providers through a single OpenAI-compatible API. You call YandexGPT 5.1 Pro there with the model id yandex/yandexgpt-5.1-pro on the /v1/chat/completions endpoint at https://llmtr.com/v1. In existing OpenAI SDK code you only change base_url, the API key and the model.
YandexGPT 5.1 Pro is the newer, lower-priced release of the YandexGPT Pro family. The LLMTR catalog describes it for business text generation, document analysis and dialogue. Yandex names it YandexGPT Pro 5.1 on its own pages; the catalog name is YandexGPT 5.1 Pro. The context window is 32,768 tokens. The model takes text in and returns text, and supports OpenAI-style tool calling, JSON output with json_object and streaming.
How to use the YandexGPT 5.1 Pro API with the OpenAI SDK
Create an API key on LLMTR and put it in the LLMTR_API_KEY environment variable. Set the OpenAI client's base_url to https://llmtr.com/v1 and pass yandex/yandexgpt-5.1-pro as the model. The Python example below reads a contract from a file, gives the model the role of a contract analyst in the system message and asks in the user message for the payment terms, deadlines and termination conditions.
The answer arrives in choices[0].message.content and the token counts in usage. prompt_tokens is the size of the request, completion_tokens the size of the answer, and the bill is calculated from these two numbers. If you store the usage values per request, you can later see what each type of document costs.
A yandex/yandexgpt-5.1-pro call with the OpenAI Python SDK: document analysis with a system and a user message, then the answer and the token usage are printed.
import os
from openai import OpenAI

client = OpenAI(base_url="https://llmtr.com/v1", api_key=os.environ["LLMTR_API_KEY"])

with open("contract.txt", encoding="utf-8") as f:
    contract = f.read()

response = client.chat.completions.create(
    model="yandex/yandexgpt-5.1-pro",
    messages=[
        {"role": "system", "content": "You are a contract analyst. Answer in short, numbered points."},
        {"role": "user", "content": "List the payment terms, deadlines and termination conditions in this contract:\n\n" + contract},
    ],
    max_tokens=1500,
)
print(response.choices[0].message.content)
print(response.usage)
Treat the 32,768-token context as a budget
The context window of YandexGPT 5.1 Pro is 32,768 tokens, and that window covers the prompt and the answer together. The system message, the user message and any earlier conversation turns count as prompt tokens; the answer takes its share of the same window. The longer the prompt, the less room is left for the answer, so leave room for it when you send a long document.
Read the real prompt size from usage.prompt_tokens instead of guessing it. A document of 8,000 tokens and an answer of 1,500 tokens use less than a third of this window. For longer documents, split the text into sections, analyze each section in its own request, then combine the short intermediate results in one final request. In multi-turn dialogue, summarize older turns to keep the prompt small.
YandexGPT 5.1 Pro pricing: one rate for input and output
On LLMTR, YandexGPT 5.1 Pro costs $6.557376 per 1M input tokens and $6.557376 per 1M output tokens. Input and output bill at one rate, and there is no cache discount. This price equals Yandex's published USD list price; Yandex quotes per 1,000 tokens, and LLMTR shows the same price per 1M tokens. The value was checked on 2026-10-12.
A worked example: a document-analysis request with 8,000 input tokens and 1,500 output tokens costs (8,000 + 1,500) x $6.557376 / 1M = $0.062295. No margin is added to this model's price; LLMTR's 8% platform fee is charged only when you top up credit.
| Property | Value |
|---|---|
| Model id | yandex/yandexgpt-5.1-pro |
| Endpoint | /v1/chat/completions |
| Context window | 32,768 tokens |
| Input and output type | text only |
| Input (per 1M tokens) | $6.557376 |
| Output (per 1M tokens) | $6.557376 |
| Cache discount | none |
| Tool calling and JSON | tools array, response_format json_object |
Streaming responses: stream and include_usage
To receive the response as a stream, add "stream": true to the request. If your application already uses a chat interface or client that reads streams, the same code works with this model too. The price is the same with or without streaming; the input and output token counts decide the amount.
To get token usage in a stream, send "stream_options": {"include_usage": true}; the usage field arrives at the end of the stream. In the curl request below, the -N flag makes curl print the output without buffering it.
A curl example that sends a streamed request to yandex/yandexgpt-5.1-pro with stream: true and include_usage.
curl https://llmtr.com/v1/chat/completions \
  -N \
  -H "Authorization: Bearer $LLMTR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "yandex/yandexgpt-5.1-pro",
    "stream": true,
    "stream_options": {"include_usage": true},
    "max_tokens": 800,
    "messages": [
      {"role": "system", "content": "You write clear business summaries."},
      {"role": "user", "content": "Summarize this meeting note in three bullet points: the team agreed to move the launch to 3 November, review the budget on Friday and hire two support agents."}
    ]
  }'
Limits: text only, no reasoning_effort, finish_reason length
YandexGPT 5.1 Pro accepts text only. A request that contains an image is refused with 400 unsupported_input and is not charged. A request that sends reasoning_effort gets 400 invalid_request, so leave that parameter out for this model in shared OpenAI SDK code.
If a response comes back with finish_reason set to length, the answer was cut. Raise max_tokens and send the request again; if the prompt is very long, shorten it as well to leave room for the answer. Use the OpenAI-style tools array for tool calling and response_format {"type": "json_object"} for JSON output.
Getting started on LLMTR: account, key and first request
Step 1: create an account at llmtr.com and top up prepaid credit. Step 2: create a key under Dashboard > API Keys; the raw key is shown only once, so store it in an environment variable such as LLMTR_API_KEY. Step 3: in your OpenAI-compatible SDK, set base_url to https://llmtr.com/v1, use yandex/yandexgpt-5.1-pro as the model and send the first request.
The same key works for every model in the catalog; each request is deducted from your credit at the catalog price in effect when it is processed.
Как подключить YandexGPT 5.1 Pro через OpenAI SDK
LLMTR (llmtr.com) — это OpenAI-совместимый API-шлюз: модель YandexGPT 5.1 Pro вызывается через него с идентификатором yandex/yandexgpt-5.1-pro. В OpenAI SDK укажите base_url https://llmtr.com/v1 и ключ LLMTR, и запросы пойдут на /v1/chat/completions. Достаточно поменять адрес, ключ и имя модели.
Контекст модели составляет 32 768 токенов. Промпт и ответ делят это окно: чем длиннее промпт, тем меньше места остаётся для ответа. Фактический размер промпта показывает поле usage в ответе, а длинные документы стоит делить на части. Цена за 1 млн токенов: вход 6,557376 $, выход 6,557376 $, скидки за кэш нет. Например, запрос на 8 000 входных и 1 500 выходных токенов стоит 0,062295 $.
Модель работает только с текстом: запрос с изображением отклоняется с ошибкой 400 и не тарифицируется, а параметр reasoning_effort не поддерживается. Вызов функций в формате OpenAI tools, ответ в JSON через response_format json_object и потоковая передача с stream работают; usage приходит в конце потока, если передать include_usage.
Практический совет: если finish_reason равен length, ответ обрезан. Увеличьте max_tokens и повторите запрос.
Чтобы начать, выполните три шага:
- Создайте аккаунт на llmtr.com и пополните баланс.
- В разделе Dashboard > API Keys создайте ключ: он показывается один раз, поэтому сохраните его в переменной окружения LLMTR_API_KEY.
- Укажите base_url https://llmtr.com/v1, модель yandex/yandexgpt-5.1-pro и отправьте первый запрос.
Call YandexGPT 5.1 Pro through LLMTR
Create an account, create an API key and send the first request to https://llmtr.com/v1 with yandex/yandexgpt-5.1-pro.
- Account. Create an account at llmtr.com and top up prepaid credit.
- API key. Create a key under Dashboard > API Keys. The raw key is shown once; store it as the LLMTR_API_KEY environment variable.
- First request. In an OpenAI-compatible SDK, set base_url to https://llmtr.com/v1 and send the first request with yandex/yandexgpt-5.1-pro as the model.
Frequently asked questions
How much does the YandexGPT 5.1 Pro API cost?
On LLMTR, per 1M tokens: $6.557376 for input and $6.557376 for output, with no cache discount. A request with 8,000 input tokens and 1,500 output tokens costs $0.062295.
Can I use YandexGPT 5.1 Pro with the OpenAI SDK?
Yes. Set base_url to https://llmtr.com/v1, use your LLMTR key as the API key and pass yandex/yandexgpt-5.1-pro as the model. Requests go to the /v1/chat/completions endpoint.
How large is the YandexGPT 5.1 Pro context window?
32,768 tokens. The prompt and the answer share that window; track the real prompt size in usage.prompt_tokens.